
The Opteryx Command Line
Opteryx Core ships a command-line interface alongside the library. It is the same engine, driven from the shell — useful for checking a dataset without opening a notebook, for wiring a query into a shell script, and for timing a query while you tune it.
What You'll Be Able to Do
By the end of this page you'll be able to:
- run a one-shot SQL statement from your shell, and quote it so your shell leaves
$names alone - query your own Parquet data by dataset name, by file path, or by folder
- filter one file into another without writing any Python
- work in the interactive session, and control how results are displayed
- write results out as JSONL or Markdown, and time a query with the built-in benchmarking mode
pip install opteryx-coreInstalling the package puts an opteryx command on your PATH. Everything below is
written as python -m opteryx, which is equivalent and works even when the script
directory isn't on your PATH:
opteryx "SELECT name, gravity FROM \$planets ORDER BY mass DESC"
python -m opteryx "SELECT name, gravity FROM \$planets ORDER BY mass DESC"
┌───┬─────────┬───────────────┐
│ │ name │ gravity │
│ │ VARCHAR │ DECIMAL(3, 1) │
╞═══╪═════════╪═══════════════╡
│ 1 │ Jupiter │ 23.1 │
│ 2 │ Saturn │ 9.0 │
│ 3 │ Neptune │ 11.0 │
│ 4 │ Uranus │ 8.7 │
└───┴─────────┴───────────────┘
[ 4 rows x 2 columns ] ( 0.94 seconds )
Virtual dataset names start with $, which most shells will try to expand. Wrap the statement in single quotes — 'SELECT ... FROM $planets' — or escape the $ as above.
Querying Your Own Data
The CLI has no way to call register_workspace(), so it falls back to reading the local filesystem relative to your current directory. A dot-separated dataset name maps to a folder of Parquet files:
cd ~/warehouse
python -m opteryx 'SELECT Company, COUNT(*) FROM data.missions GROUP BY Company'
data.missions reads ./data/missions/ — the folder, not a single file. This is the same resolution the library uses when no workspace is registered; see Querying Local Data for the details, and Connectors for reaching anything that isn't local disk, which needs Python.
Reading Files by Path
Dataset names are convenient when your data is already laid out as folders under the directory you're working in. When it isn't — a file someone just sent you, something sitting in ~/Downloads, one Parquet file out of a folder of forty — the READ_* table functions take a path directly and go in the FROM clause wherever a table name would:
python -m opteryx "SELECT Company, Rocket, Price FROM READ_PARQUET('space_missions.parquet') LIMIT 5"There is one per format — READ_PARQUET, READ_CSV and READ_JSONL — and they are what make the CLI useful for files you have not organised yet. Filter and column pushdown still apply, so naming the columns you want is worth doing on a large file even from the shell.
CSV and JSONL take optional arguments for the things those formats leave ambiguous:
python -m opteryx "SELECT * FROM READ_CSV('orders.tsv', separator => '\t', has_header_row => false) LIMIT 5"
python -m opteryx "SELECT id, status FROM READ_JSONL('events.jsonl', ignore_errors => true) LIMIT 5"
Parquet needs none — its schema comes out of the file's own footer. The full argument lists are on the READ_CSV and READ_JSONL reference pages.
Because SQL string literals need single quotes, wrap the whole statement in double quotes at the shell — and remember to escape any $ in a virtual dataset name, since double quotes don't stop the shell expanding it.
Reading a Folder
A path containing *, ? or [ matches multiple files and reads their combined content as one relation:
python -m opteryx "SELECT COUNT(*) FROM READ_PARQUET('data/missions/*.parquet')"
python -m opteryx "SELECT Company FROM READ_JSONL('data/logs/*.jsonl') LIMIT 5"
Wildcards work at more than one level, which is how you read across a partitioned layout:
python -m opteryx "SELECT COUNT(*) FROM READ_PARQUET('data/*/*.parquet')"Two things to know about paths here. A bare folder name is not a glob — READ_PARQUET('data/missions') fails, because it names a directory rather than a pattern; write data/missions/*.parquet. And a glob needs a directory component in front of it, so a pattern matching files in your current directory has to be written ./missions-*.parquet rather than missions-*.parquet.
For Parquet, files matched by a glob that aren't Parquet are skipped. For CSV and JSONL they aren't, so match on the extension rather than relying on a bare *. Every matched file's schema has to agree with the first one's — a file that disagrees fails the query instead of quietly dropping or nulling the columns.
Remote paths work the same way. https:// URLs and public gs:// objects are read anonymously, so a URL someone gives you is queryable without downloading it first:
python -m opteryx "SELECT COUNT(*) FROM READ_PARQUET('https://example.com/data/packages.parquet')"Globs are not supported for gs:// paths — listing a bucket needs a permission an anonymous read doesn't have.
Filtering a File Into Another File
READ_* and --o together make the CLI a filter: read one format, cut it down with SQL, write another.
python -m opteryx --o recent.jsonl \
  "SELECT Company, Mission, Lauched_at
     FROM READ_PARQUET('data/missions/*.parquet')
    WHERE Mission_Status = 'Success'"
Formats mix freely in a single query, so joining a Parquet extract against a JSONL log needs no conversion step first:
python -m opteryx \
  "SELECT p.Mission, j.status
     FROM READ_PARQUET('data/missions/*.parquet') AS p
     INNER JOIN READ_JSONL('data/logs/*.jsonl') AS j
       ON p.Mission = j.mission"
For a straight format conversion with no SQL in it, the rugo command is the lighter tool — it doesn't plan a query, and it streams rather than materialising.
The Interactive Session
Run it with no SQL argument and you get a REPL:
python -m opteryx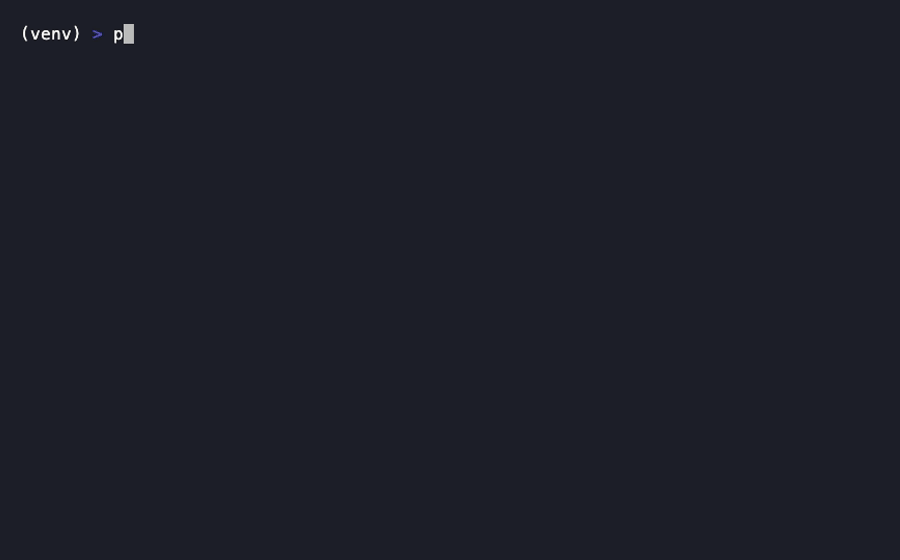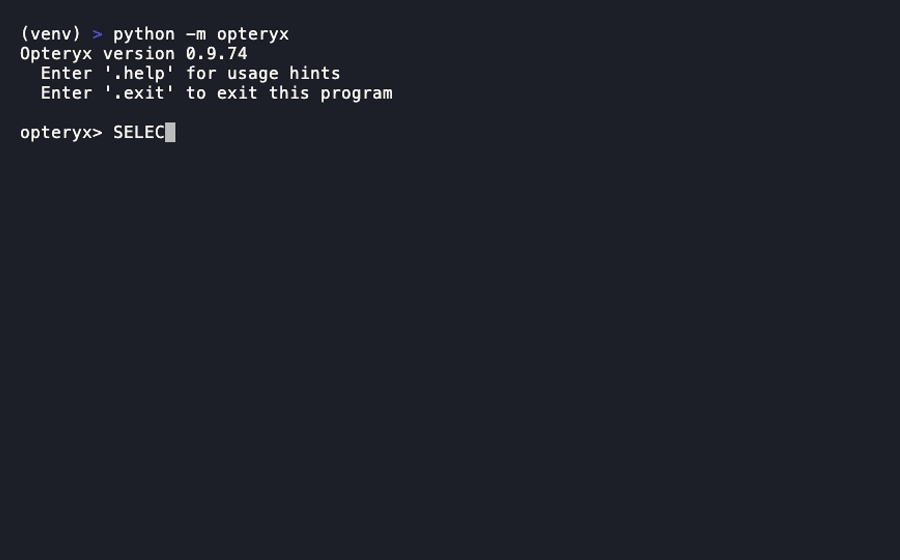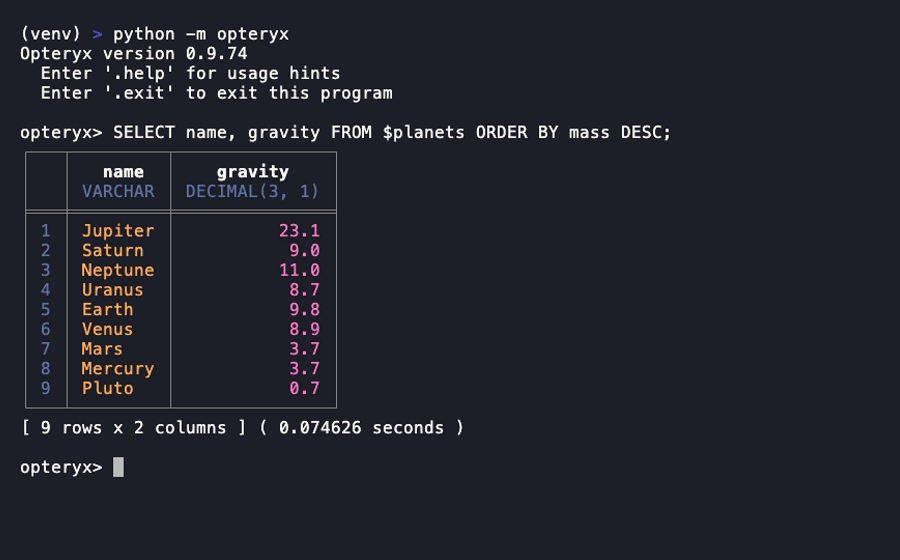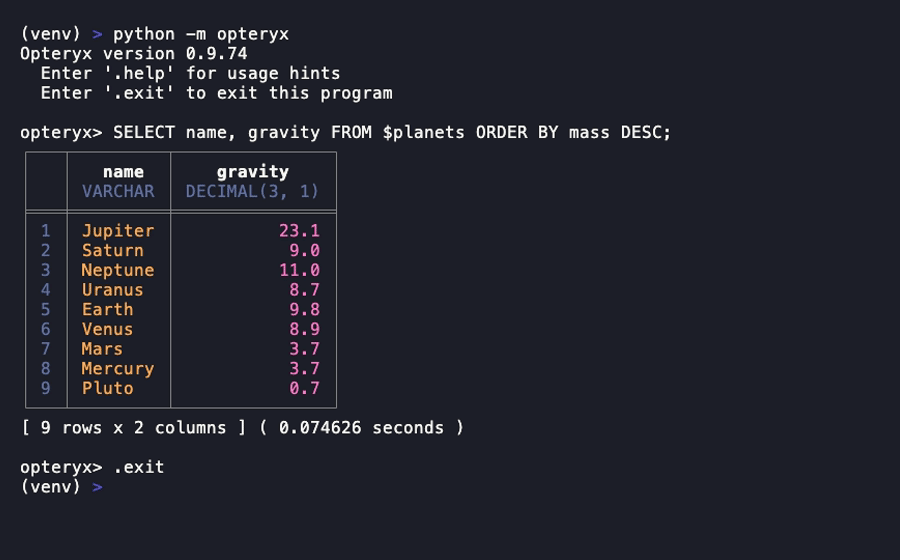
Each statement runs as you enter it, with a row count and elapsed time printed underneath. Two dot commands are recognised — .help for the usage hints and .exit (or .quit) to leave. Errors are reported and the session continues, so a typo doesn't cost you the session.
Writing Results to a File
By default results are rendered as a table on the console. --o writes them to a file instead, choosing the format from the extension:
python -m opteryx --o results.jsonl "SELECT * FROM data.missions WHERE Company = 'SpaceX'"
python -m opteryx --o summary.md "SELECT Company, COUNT(*) FROM data.missions GROUP BY Company"
Only .jsonl and .md are supported — anything else is rejected rather than guessed at. JSONL is the one to pipe onward; Markdown is for pasting a result into a document or an issue. --o is not accepted in REPL mode, since there is no single result to write.
Controlling the Display
Console output is coloured and width-limited by default, which is what you want at a terminal and not what you want in a log file or a pipe:
python -m opteryx --no-color --no-stats 'SELECT * FROM $planets'--no-color drops the ANSI codes, and --no-stats suppresses the trailing [ n rows x n columns ] line. --max_col_width sets where long values are truncated, defaulting to 64 characters — raise it when a column you care about is being cut off.
Timing a Query
--cycles runs the same statement repeatedly and reports each run's wall time instead of its results:
python -m opteryx --cycles 5 'SELECT Company, COUNT(*) FROM data.missions GROUP BY Company'[1.284,0.671,0.658,0.662,0.655]
Each cycle opens its own session and drains the result to morsels without rendering anything, so the numbers reflect the engine rather than the table formatter. The first is normally the slowest — caches are cold and the file footers have not been read yet. This is the quickest way to see whether a rewrite or a config change actually moved the needle; for why a query is slow, EXPLAIN and Troubleshooting Queries will tell you more than a timing will.
Options
| Option | What it does |
|---|---|
sql |
The statement to run. Omit it for the REPL |
--o |
Write results to a file — .jsonl or .md (console output when unset) |
--color / --no-color |
Colourised table output (on by default) |
--no-stats |
Suppress the row/column/timing line |
--max_col_width |
Truncate column values beyond this width (default 64) |
--cycles |
Run the statement N times and report timings instead of results |
Comments are stripped from the statement before it is planned, so a query pasted out of a .sql file runs as-is.